Robbyant, the embodied AI company inside Ant Group, has released a model meant to give robot hands a shared sense of touch. LingBot-Touch, published on November 9 with a technical report, code and two sets of weights under the Apache 2.0 license, turns the signals from three different kinds of tactile sensor into one common representation that a robot policy can read. Robbyant says adding it lifted four different control policies by roughly 14 to 26 percentage points across 26 real-robot tasks.
Touch is the sense most robot foundation models still skip. NVIDIA’s GR00T 2 whitepaper, released at CoRL the same day, lists among its limits that the model “does not take touch as input.” LingBot-Touch tries to make touch data reusable across sensors and hands, the way pretrained vision models made camera data reusable. The release is genuinely open and the experiments include the right control. The scores, though, need a careful read before anyone quotes them.
- What: LingBot-Touch, an open tactile foundation model from Robbyant (Ant Group) that encodes magnetic, piezoresistive and visuotactile sensor signals into shared tokens for robot policies. Released November 9, 2026, under Apache 2.0.
- Trained on: 4,983 hours of touch recordings (464,431 episodes, about 1.33 billion frames) from tactile gloves and robot hands. The smallest encoder has 5.46 million parameters.
- Results (Robbyant’s tests): across 26 real tasks on two dexterous hands, adding it raised four policies’ average scores by 13.9 to 24.8 points. Physical Intelligence’s π0.5 went from 48.1% to 69.9%.
- The catch: the task “success rates” give partial credit for completed steps, Robbyant ran every test, and only two hands were tried. The weights downloaded without a login on November 10, but the training data and training code aren’t released.
One encoder for three kinds of fingertip sensor
The problem LingBot-Touch goes after is fragmentation. Commercial tactile sensors work on different physics. Piezoresistive pads change resistance under pressure. Magnetic sensors report three-axis readings. Visuotactile fingertips, like those on the Sharpa Wave hand, image their own deformation with an internal camera. Each produces a different data format with a different layout of taxels, the touch equivalent of pixels, so a model trained on one sensor usually can’t read another.
Robbyant’s answer has three parts, according to its report. Every sensor’s taxels are mapped into a shared “canonical fingertip space,” so the model sees positions on a finger rather than indices in a sensor array. Separate tokenizers handle each sensor type and feed one shared transformer. And the model is trained in the JEPA style, predicting the hidden parts of a touch recording in a learned representation space rather than reconstructing the raw signal. The report says that choice mattered: a reconstruction-style VAE objective got worse as data grew.
The training corpus breaks down like this, per Robbyant’s project page:
| Sensor type | Hours | Episodes |
|---|---|---|
| Piezoresistive | 2,197 | 86,906 |
| Magnetic | 1,136 | 294,871 |
| Visuotactile | 1,650 | 82,654 |
| Total | 4,983 | 464,431 |
Five thousand hours is tiny next to the video corpora behind vision-based robot models. Nature Will says its Natura-1 hand model learned from more than a million hours of first-person video (our Natura-1 story), and NVIDIA’s GR00T 2 used 402,730 hours of human video. But touch data is far harder to collect, and Robbyant calls its corpus the first at a scale where representation learning for touch becomes possible. That’s a claim, not a census, but we haven’t seen a larger published one.
What adding touch did on 26 real tasks
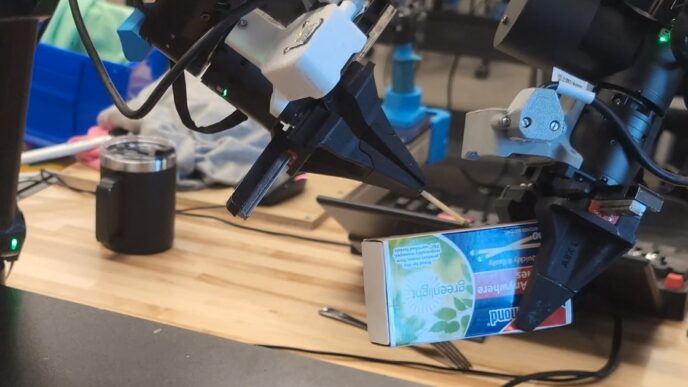
Robbyant tested on two dual-arm systems. One uses Sharpa Wave hands, whose visuotactile sensors appear in the training data. The other uses XHand1 hands, whose magnetic sensor model never appeared in the training data. There were 26 tasks, 20 on Sharpa Wave and 6 on XHand1, each run for 20 trials, and they were picked “so that touch matters”: turning a single page, ejecting an SD card, twisting a cap, closing a zipper, sorting mahjong tiles by feel.
Four existing policies were each post-trained three ways on the same demonstrations, 200 per task or 500 for two-handed tasks: with no touch input, with the raw tactile signal, and with frozen LingBot-Touch tokens. They were Diffusion Policy, Physical Intelligence’s π0.5, Robbyant’s own LingBot-VLA and a model called T-Rex. Averaged over all 26 tasks:
| Policy | No touch | Raw touch signal | With LingBot-Touch |
|---|---|---|---|
| Diffusion Policy | 21.6% | 28.7% | 35.6% |
| π0.5 | 48.1% | 54.7% | 69.9% |
| LingBot-VLA | 48.3% | 56.5% | 73.1% |
| T-Rex | 45.4% | 56.6% | 68.6% |
The no-touch and LingBot-Touch columns are from Section 5.2 of the report. The raw-signal column is our calculation from its Table 2, weighting the 20 Sharpa Wave and 6 XHand1 tasks, and it matches the gains the report states. That middle column is the important one. It separates having touch from understanding it. Feeding raw tactile data helped about half as much at best, and it hurt in 22 of 104 task-policy pairs: LingBot-VLA fell from 28.8% to 5.0% on mahjong sorting when given the raw signal. With the frozen tokens, the report says, a policy was at or above its no-touch score in 99 of 104 pairs.
The unseen hand is the strongest evidence. On XHand1’s six tasks, the raw signal changed the four policies’ scores by +4.6, -1.7, 0.0 and +2.0 points. LingBot-Touch tokens computed from the same signal added 16.3, 24.5, 17.8 and 13.8, with no sensor-specific training. The biggest single gains came at moments a camera can’t judge, Robbyant says, such as whether a spray trigger has been pulled far enough (42.5% to 87.5% for LingBot-VLA) or whether an SD card has released (32% to 92% for T-Rex). In simulation, reinforcement learning with LingBot-Touch features succeeded 69% of the time across 12 dexterous tasks, against 46% with a task-specific CNN and 21% with no touch.
Why a 70% score isn’t a 70% success rate
Here’s the part the headline numbers don’t tell you. The report’s appendix scores each task in points for completed steps. Single-page turning, for example, earns “1 point each” for approaching the edge, moving the page by contact, crossing the spine with one page and completing the turn, for a total of 4. The “success rates” in Table 2 are those points as a share of the maximum over 20 trials. You can see it in the numbers: with 20 pass-or-fail trials, every score would be a multiple of 5%, yet the table is full of values like 3.75% and 21.25%. So when π0.5 scores 69.9% with LingBot-Touch, that doesn’t mean it finished seven tasks in ten. A run that grabs the bag but never seals it still earns points. The report doesn’t give a full-completion rate.
Partial credit is a reasonable way to measure progress on hard tasks, and it applies equally to every column, so the comparisons inside the table hold. It just isn’t what most readers hear in “success rate.”
There are other cautions. Robbyant chose the tasks, ran every trial and post-trained every baseline, and one of the four policies is its own. The π0.5 results are Robbyant’s fine-tune with 200 demonstrations, not Physical Intelligence’s numbers.
The release’s “approximately 14 to 26 percentage points” is also a little generous. The report’s own 26-task averages give gains of 13.9 to 24.8 points; the largest single-hand gain we found in Table 2 is 26.9 points, for LingBot-VLA on Sharpa Wave (45.60% to 72.51%). And Table 2 used the Tiny encoder pretrained on 4,000 hours, while the released checkpoints are described as trained on about 5,000. On a five-task check in the report, that extra data moved LingBot-VLA from 81.4% to 82.2%, so the gap looks small.
Even with those caveats, this is better evidence than most touch claims we’ve covered. NEURA said its Neuron AI model adds touch, force and sound, but its launch release included no benchmark isolating what touch contributes (our Neuron AI story). Robbyant ran the raw-signal control, tested a sensor the model never saw, and published per-task numbers, including the 5 pairs where LingBot-Touch scored below the no-touch policy. The report also lists its own limits: only two hand designs, no capacitive sensors because the available recordings didn’t meet Robbyant’s quality bar, and coverage focused on fingertips, with palms and the rest of the fingers underrepresented.
What LingBot-Touch actually lets you download
The open part is real. The GitHub repository, created November 9 under Apache 2.0, holds the inference code, adapters for Sharpa Wave and XHand data, and 120 single-hand sample recordings. On Hugging Face, the Tiny and Small bundles each contain one encoder file and one config file, also under Apache 2.0, about 22 MB and 87 MB in total. The GitHub readme says access “requires an account with permission,” but on November 10 Hugging Face listed both repositories as not gated and the files downloaded without a login.
What isn’t included matters for anyone hoping to build on it. The model cards say the bundles hold only the frozen encoder, with no predictors, task heads, training configurations or logs, and the 4,983-hour corpus isn’t released. You can extract touch features and train your own policy on top. You can’t retrain or extend the encoder the way Robbyant did. A new sensor layout also needs a verified geometric calibration into the canonical fingertip space before the model can read it, per the readme.
That’s still a useful offer for the people Robbyant is pitching: hand makers and robot teams who want touch without building a tactile model from scratch. In its press release, Robbyant says sensor and hand makers can choose hardware on cost while robotics teams keep their own policies. Touch hardware is spreading: Unitree’s Dex5-S hand is listed from $6,350, with touch sensing on the Pro version, and Sharpa has shown a 21-joint hand with full-hand touch sensing (our robot hand comparison). A shared encoder is one way those different sensors could feed the same software.
What to watch
The next test is someone other than Robbyant. The report’s tables give outside labs a baseline to try on other hands and sensors, and the encoder is small enough to run alongside a large policy: Robbyant says it adds 0.13% to 0.16% to the parameter counts of the VLAs it tested. Watch for independent results on a third hand design, for a full-completion metric alongside the partial-credit scores, and for whether NVIDIA’s GR00T 2 code, due in December, or Physical Intelligence’s next model adds touch as an input. If the big labs do, the question becomes whose touch representation they use.
Frequently asked questions
What is LingBot-Touch?
LingBot-Touch is a tactile foundation model from Robbyant, Ant Group’s embodied AI company, released on November 9, 2026. It converts readings from magnetic, piezoresistive and visuotactile touch sensors into shared tokens that robot control policies can use alongside cameras.
Is LingBot-Touch open source?
The inference code and the Tiny and Small encoder weights are released under the Apache 2.0 license on GitHub, Hugging Face and ModelScope. The training code and the 4,983-hour training dataset aren’t released, so you can use the encoder but not retrain it.
Which robot hands and sensors does LingBot-Touch work with?
Robbyant tested it on the Sharpa Wave hand, whose visuotactile sensors were in the training data, and the XHand1, whose magnetic sensor model wasn’t. Other hands can work if their sensor layout is calibrated into the model’s shared fingertip space. Capacitive sensors aren’t covered yet.
How much does LingBot-Touch improve robot performance?
In Robbyant’s own tests on 26 real tasks, it raised four policies’ average scores by 13.9 to 24.8 points. Those scores give partial credit for completed steps, so they aren’t the share of tasks finished.
Who makes LingBot-Touch?
Robbyant, a Shanghai company within Ant Group that builds the LingBot family of robot models, including LingBot-VLA. The LingBot-Touch report lists 19 authors.
Sources
- Han et al. (Robbyant): “Learning Heterogeneous Tactile Representation for General Dexterous Manipulation,” arXiv 2611.12806, November 9, 2026 (Secs. 1, 5 and 6, Tab. 2, Tab. 7, App. B)
- Robbyant: LingBot-Touch project page (corpus figures, task list, overview video)
- GitHub: Robbyant/lingbot-touch (Apache 2.0, created November 9, 2026)
- Hugging Face: robbyant/lingbot-touch-tiny and robbyant/lingbot-touch-small model cards (Apache 2.0, checked November 10, 2026)
- Business Wire: “Robbyant Releases LingBot-Touch to Bring General-Purpose Touch Perception to Robots,” November 9, 2026
- Zhidx (Chinese-language tech outlet): LingBot-Touch release coverage, November 10, 2026
- NVIDIA GEAR: GR00T 2 whitepaper, November 2026 (limitations section)
All sources accessed November 10, 2026.
Last updated: November 10, 2026. To report an error, see our corrections page. Articles are drafted with AI assistance and reviewed and edited by an editor; see our editorial policy.