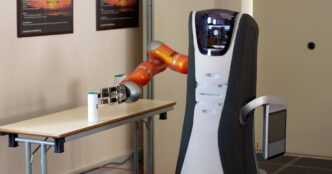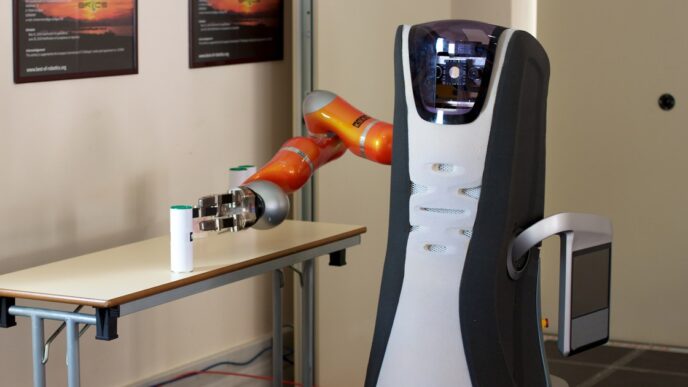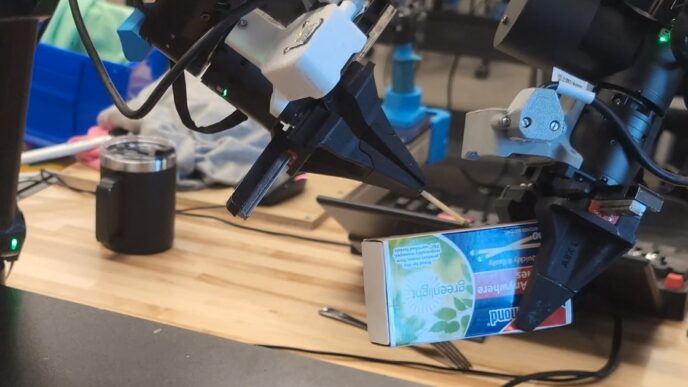
In July 2023, Google DeepMind showed a robot arm following the instruction “pick up the extinct animal.” Nothing in its robot training data taught it what an extinct animal is. The model behind it, RT-2, brought that knowledge from the web. Three years later, robot AI models walk humanoids around rooms, run on robots their makers never trained them on, and can be downloaded or rented through an API.
This robot foundation models timeline covers the main releases from 2022 to November 2026, in order: what each model was, who built it, what it showed and whether you can use it. Every date comes from the paper, blog or model page of the company or lab that made it.
- Where it started: RT-1 (December 2022) and RT-2 (July 2023) from Google showed one large model could control a robot, and that web knowledge could carry over to robot actions.
- The big shifts: shared datasets (Open X-Embodiment, 2023), open models (Octo, OpenVLA, π0, 2024), humanoid “two-system” brains (Helix, GR00T N1, 2025) and whole-body control (Gemini Robotics 2, 2026).
- What you can use today: open weights such as OpenVLA, openpi, GR00T N1.7 and Unitree’s UnifoLM-WLA-1.0; Google’s and Physical Intelligence’s newest models are limited to partners or a beta.
- The catch: almost every success rate in this timeline was measured by the team that built the model, on tasks it chose.
The robot foundation models timeline at a glance
| Date | Model | Made by | Why it mattered |
|---|---|---|---|
| Dec 2022 | RT-1 | One transformer trained on 130,000+ real robot episodes | |
| Mar 2023 | Diffusion Policy | Columbia, Toyota Research Institute, MIT | Generated robot actions the way image models generate pictures |
| Jul 2023 | RT-2 | Google DeepMind | Named the vision-language-action (VLA) model |
| Oct 2023 | Open X-Embodiment / RT-X | 21 institutions | Pooled data from 22 robot types |
| May-Jun 2024 | Octo, OpenVLA | University-led teams | First widely used open generalist models |
| Oct 2024 | π0 | Physical Intelligence | Flow-matching actions on top of a vision-language model |
| Feb-Mar 2025 | Helix, GR00T N1, Gemini Robotics | Figure, NVIDIA, Google DeepMind | Foundation models built for humanoids |
| Apr-Sep 2025 | π0.5, Gemini Robotics 1.5 | Physical Intelligence, Google DeepMind | Generalizing to new homes; planning agents |
| 2026 | π0.7, Gemini Robotics 2, UnifoLM-WLA-1.0, GR00T N1.7 | Physical Intelligence, Google DeepMind, Unitree, NVIDIA | Whole-body control, open humanoid weights, paid access |
2022 to 2023: proving one model could run a robot
RT-1 (December 2022). Google’s Robotics Transformer was trained on more than 130,000 episodes covering more than 700 tasks, collected with a fleet of 13 robots over 17 months. The point was scale: instead of one model per task, one model learned many, and it got better with more and more varied data.
Diffusion Policy (March 2023). Researchers from Columbia, Toyota Research Institute and MIT treated a robot’s next movements as something to generate step by step, the way diffusion models generate images. Across 12 tasks from four benchmarks they reported an average improvement of 46.9% over earlier methods. The idea of generating smooth chunks of motion runs through most of the later models. Our diffusion policy explainer covers how it works.
RT-2 (July 28, 2023). Google DeepMind fine-tuned large vision-language models on robot data and wrote robot actions as text tokens, so one model could answer questions and move an arm. The paper named this class of model the vision-language-action model, or VLA. In 6,000 evaluation trials, RT-2 handled objects and commands that weren’t in its robot training data. See our RT-2 explainer for the details.
Open X-Embodiment and RT-X (October 2023). Robot data was scarce and scattered across labs, so 21 institutions pooled theirs: 22 robot types, 527 skills and 160,266 tasks in one standard format. Models trained on the mix, called RT-X, improved on several robots by learning from the others. Our Open X-Embodiment guide explains what is inside and its limits.
2024: open models anyone could download
Octo (May 2024). A team led by UC Berkeley and Stanford researchers released Octo, an open-source generalist policy trained on 800,000 trajectories from the Open X-Embodiment data. It could take language commands or goal images and be fine-tuned to new robots and sensors.
OpenVLA (June 2024). A Stanford-led team with UC Berkeley, Toyota Research Institute and others brought the RT-2 recipe into the open with OpenVLA, a 7-billion-parameter VLA built on Meta’s Llama 2 with DINOv2 and SigLIP vision encoders, trained on 970,000 real robot demonstrations. Its authors also showed how to fine-tune it cheaply for new tasks, which made it a common starting point for university labs.
π0 (October 31, 2024). Physical Intelligence, a San Francisco startup, attached an “action expert” that uses flow matching, a relative of diffusion, to a pre-trained vision-language model. It trained on data from single-arm, dual-arm and mobile robots and showed laundry folding, table cleaning and box assembly. The company later released code and weights through its openpi repository. Our π0 explainer covers the architecture.
2025: foundation models built for humanoids
Helix (February 20, 2025). Figure’s VLA split the job in two: a 7-billion-parameter “System 2” that understands the scene at 7 to 9 times a second, and an 80-million-parameter “System 1” that turns that into upper-body motion 200 times a second. Figure said it was trained on about 500 hours of teleoperated behavior.
GR00T N1 (March 18, 2025). NVIDIA’s open humanoid model used the same two-speed idea, with a diffusion transformer generating motor actions. It was trained on a mix of real robot data, human videos and synthetic data, and demonstrated on a Fourier GR-1 humanoid.
Gemini Robotics (March 2025). Google DeepMind built a VLA on Gemini 2.0, plus Gemini Robotics-ER, a model for spatial reasoning such as pointing and 3D object detection. The report says the VLA could learn some new short tasks from as few as 100 demonstrations.
π0.5 (April 22, 2025) and Gemini Robotics 1.5 (September 25, 2025). Physical Intelligence co-trained π0.5 on robot data, web data and high-level task predictions so it could clean up homes it had never seen. Google’s 1.5 release paired its VLA with a reasoning model that plans multi-step tasks and can use tools such as web search, an agent-style design.
2026: whole bodies, open weights and paid access
π0.7 (April 16, 2026). Physical Intelligence described it as a “steerable” model with “a step-change in generalization.” In October the company opened a Pi API beta for fine-tuning and hosted inference, with no public price.
GR00T N1.7 (2026). NVIDIA’s current open checkpoint is a 3-billion-parameter model on Hugging Face, last updated in April 2026, with N1.5 and N1.6 kept as earlier releases. Our GR00T explainer covers what is open and what isn’t.
Gemini Robotics 2 (July 30, 2026). Google DeepMind’s three-model family can control a full humanoid “from feet to fingertips,” including walking, crouching and manipulating objects on Apptronik’s Apollo 2. Google’s own chart shows medium to high success on whole-body and gripper tasks and says multi-finger dexterity “remains challenging.” The reasoning model, ER 2, is available in Google AI Studio; the VLA and on-device models are limited to early-access partners. More in our Gemini Robotics 2 guide.
Open humanoid weights and world action models (September 2026). Unitree released UnifoLM-WLA-1.0, a 6-billion-parameter model for its G1 humanoid under the Apache 2.0 license, without published success rates. Black Forest Labs released FLUX 3 Action, a world action model that predicts video of what happens next along with the robot’s actions, a possible challenger to the VLA design.
Four patterns in the timeline
- Actions became their own output. RT-2 wrote actions as words. Later models such as π0 and GR00T N1 generate smooth chunks of motion with flow matching or diffusion, which suits fast, continuous control.
- Data became the bottleneck. The jump from RT-1’s 130,000 episodes to pooled datasets, human video and simulation reflects how hard real robot data is to collect.
- Two speeds became standard. A slow model that understands the scene and a fast one that moves the body, first explicit in Helix and GR00T N1, now shapes most humanoid stacks.
- Openness split. Academic labs, NVIDIA and Unitree publish weights; Google and Physical Intelligence keep their newest models behind partner programs or an API.
One thing hasn’t changed since 2022: evidence. Nearly every result above comes from the model’s makers, on robots and tasks they picked. Shared benchmarks and blind evaluations are still young, so treat headline success rates as claims to check, and see our guide to reading robot demos for what to look for.
What to watch next
Three things will shape the next entries: whether Google and Physical Intelligence open their 2026 models beyond partners, whether world action models beat VLAs on real robots rather than in simulation, and whether any maker publishes success and intervention rates from paid work instead of lab demos. We will add new releases to this timeline as they ship.
Frequently asked questions
What was the first robot foundation model?
There is no single agreed first. Google’s RT-1, published in December 2022, is often cited as the first large transformer trained on broad real-robot data to control many tasks. RT-2, in July 2023, was the first model its authors called a vision-language-action model.
What is the difference between RT-2 and OpenVLA?
Both are vision-language-action models that turn camera images and text instructions into robot actions. RT-2 was Google DeepMind’s research model and was not released. OpenVLA, released by a Stanford-led research team in June 2024, is a 7-billion-parameter open-source model trained on 970,000 demonstrations that anyone can download and fine-tune.
Which robot foundation models are open source in 2026?
Downloadable options include Octo, OpenVLA, Physical Intelligence’s openpi release of π0-family models, NVIDIA’s GR00T N1.7 and Unitree’s UnifoLM-WLA-1.0. Check each license before commercial use. Google’s Gemini Robotics 2 VLA is available only to early-access partners.
When was Gemini Robotics 2 released?
Google DeepMind announced Gemini Robotics 2 on July 30, 2026. It includes a VLA model, a reasoning model called Gemini Robotics ER 2 that is available in Google AI Studio, and an on-device model. The VLA and on-device models are limited to early-access partners.
Are robot foundation model success rates independently verified?
Mostly not. Nearly all published success rates come from the teams that built the models, on tasks and robots they selected. Shared benchmarks and blind evaluations exist but are new, so treat a headline number as a company or lab claim unless an outside group reproduced it.
Sources
- Brohan et al., “RT-1: Robotics Transformer for Real-World Control at Scale,” arXiv:2212.06817 and RT-1 project page
- Chi et al., “Diffusion Policy: Visuomotor Policy Learning via Action Diffusion,” arXiv:2303.04137
- Brohan et al., “RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control,” arXiv:2307.15818
- Open X-Embodiment Collaboration, “Open X-Embodiment: Robotic Learning Datasets and RT-X Models,” arXiv:2310.08864
- Octo Model Team, “Octo: An Open-Source Generalist Robot Policy,” arXiv:2405.12213
- Kim et al., “OpenVLA: An Open-Source Vision-Language-Action Model,” arXiv:2406.09246
- Black et al., “π0: A Vision-Language-Action Flow Model for General Robot Control,” arXiv:2410.24164
- Figure: “Helix: A Vision-Language-Action Model for Generalist Humanoid Control,” February 20, 2025
- NVIDIA, “GR00T N1: An Open Foundation Model for Generalist Humanoid Robots,” arXiv:2503.14734
- Gemini Robotics Team, “Gemini Robotics: Bringing AI into the Physical World,” arXiv:2503.20020
- Physical Intelligence, “π0.5: a Vision-Language-Action Model with Open-World Generalization,” arXiv:2504.16054
- Google DeepMind: “Gemini Robotics 1.5 brings AI agents into the physical world,” September 25, 2025
- Physical Intelligence research blog (π0.7, April 16, 2026; Pi API beta, October 13, 2026)
- NVIDIA Isaac GR00T repository (GR00T N1.7) and GR00T-N1.7-3B model page
- Google DeepMind: “Gemini Robotics 2 brings whole body intelligence to robots,” July 30, 2026
- Unitree: UnifoLM-WLA repository
All sources accessed November 4, 2026.
Last updated: November 4, 2026. To report an error, see our corrections page. Articles are drafted with AI assistance and reviewed and edited by an editor; see our editorial policy.